Edge inference
CompleteCosmos First-Timers Guides
Two Colab notebooks that take a developer from an empty session to working image and video calls on Cosmos Reason 2 and Cosmos3-Edge, with every setting measured for what it does to accuracy and response time.
Measured results
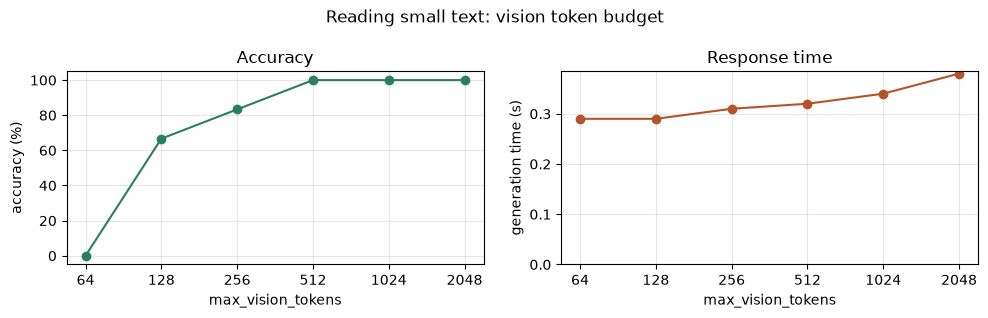
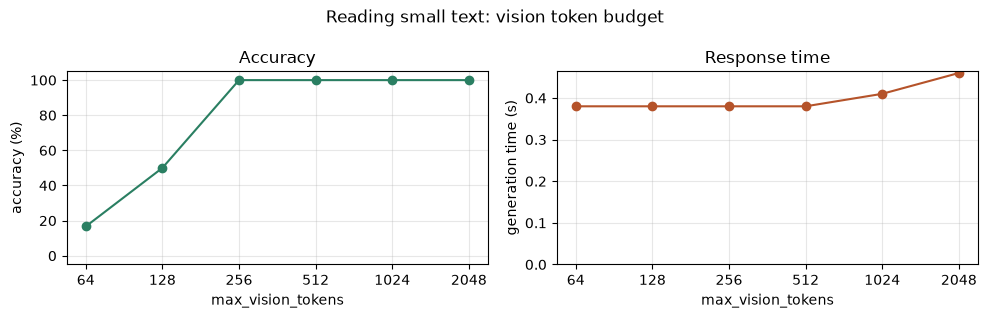
- Vision token budget, Cosmos3-Edge0 of 6 to 6 of 6Reading six small labels, 64 to 512 tokens, RTX 5090, 2026-11-15
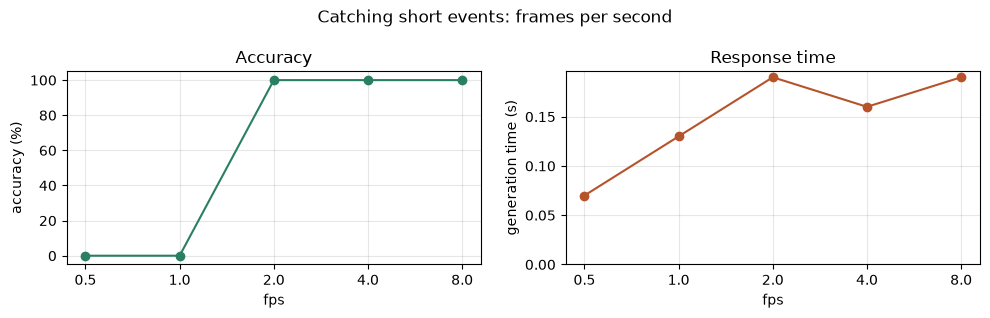
- Frame rateBelow 2 fps, 0 foundDigits shown for half a second, both models
- Writing speed147 against 113 tokens/sCosmos3-Edge against Cosmos Reason 2 (2B), RTX 5090
- ColabEvery cell ranT4 and A100 runtimes, both notebooks
- SimulationEmpty Colab session
- SimulationInstall and load the model
- Edge computeImage and video calls
- Edge computeOne setting changed at a time
- PhysicalScored against a known answer
Hardware
The notebooks were measured on an RTX 5090 workstation, and both ran start to finish on Google Colab’s T4 and A100 runtimes. The Colab runs were not recorded, so every number here is from the workstation. The server tests used vLLM on the same workstation.
Workload
Two guides, built to be read in either order and linked to each other: Cosmos Reason 2 for First-Timers and Cosmos 3 Edge for First-Timers. Each starts from an empty Colab session, gets to a working image and video call, and then changes one setting at a time: vision token budget, frames per second, cropping, sampling, thinking, precision, batching. Every test has a known answer, so each setting is scored, not described.
What was measured
- The vision token budget decides whether small text is readable. Cosmos3-Edge went from 0 of 6 labels at 64 tokens to 6 of 6 from 512; Cosmos Reason 2 went from 1 of 6 to 6 of 6 at 256.
- Below 2 frames per second, both models miss digits that are on screen for half a second.
- On the same workstation, Cosmos3-Edge wrote 147 tokens a second against 113 for Cosmos Reason 2 (2B), and took 4.9 GB on the GPU against 4.3 GB.
What failed
- 4-bit loading, which works on Cosmos Reason 2 at a small cost in accuracy, returned no readable text on Cosmos3-Edge, with no error. The cause is not established.
- Cosmos3-Edge thinks by default, and the switch is in the chat template. With the switch off, an instruction in the prompt alone did not turn thinking on. With greedy decoding and thinking on, it looped to the token limit on one video prompt.
- Setting the frame rate the way NVIDIA’s prompt guide shows failed on vLLM 0.33.0; a different request option worked.
Result
Both notebooks are public and open in Colab with one click. They are small tests, 4 to 12 questions each: they show what a setting does, not a benchmark score.
Evidence
The charts behind the results